01 · Start with the question that matters
“How much carbon is in this forest?” and “How many credits can this project receive?” require different evidence. A forest can contain a great deal of carbon without that entire stock being available for a new credit claim.
| Quantity | Plain meaning | What this workbench does |
|---|---|---|
| Carbon stock | Carbon held in the included tree pools at a date, expressed here as tCO₂e | Converts supplied biomass or accepts a compatible total tree-stock estimate |
| Monitoring-period change | The difference between comparable dates, after applicable deductions | Calculates a signed estimate from the supplied inputs |
| Issued credits | Units approved and recorded through the relevant programme | No registry connection; never inferred from the estimate |
- Define an eligible project and its boundary
- Measure comparable tree stocks at two dates
- Apply the selected methodology and required deductions
- Independent review and programme approval
- Registry issuance is a separate external step
The order matters. Drawing a polygon establishes a calculation area; it does not establish land rights. Finding trees establishes vegetation; it does not establish additionality, meaning the benefit required beyond the applicable baseline. A registration count is administrative evidence, not proof that the same carbon has never been claimed elsewhere.
02 · Follow one tonne through the calculation
Trees are measured before they become numbers on a carbon ledger. Diameter and height feed an allometric equation: a relationship developed from measured trees to estimate dry biomass. “Dry” matters because water adds weight without adding the carbon being estimated. The equation must fit the forest and tree group.
The current importer supports the TGO appendix equation for mixed deciduous and dry dipterocarp trees, with DBH at least 4.5 cm. It estimates aboveground biomass from measured trees, then expands the plot total by surveyed area under a single representative-stratum assumption. It does not prove that the sampling design is representative. Empty plots cannot be represented by the current CSV format; do not quietly drop them. See the user guide for coefficients, units and exclusions.
- Diameter (cm) + height (m) in measured plots
- Suitable tree equation → dry aboveground biomass
- Expand by surveyed area within a representative stratum
- Include roots using the applicable root:shoot ratio
- Multiply by carbon fraction, then 44/12 → tCO₂e
For the general-tree factors in TGO tree tool v2, roots are estimated at 0.27 times aboveground biomass and the carbon fraction is 0.47. The factor 44/12 converts carbon mass to the corresponding CO₂ mass. Other tree groups use other factors. If an input already includes roots or is already in tCO₂e, applying those conversions again inflates the answer.
A worked example you can reproduce
Assume the same project's dry aboveground biomass rises from 1,000 to 1,100 tonnes. Keep factors and included pools unchanged. This is synthetic teaching data, not a measured Thai forest.
| Step | Calculation | Result |
|---|---|---|
| Aboveground increase | 1,100 − 1,000 | 100 t dry biomass |
| Include estimated roots | 100 × 1.27 | 127 t total biomass |
| Convert to carbon | 127 × 0.47 | 59.69 tC |
| Convert to CO₂ | 59.69 × 44/12 | 218.8633 tCO₂ |
This is the stock increase before applicable deductions. For an exactly five-year duration, its average is 43.7727 tCO₂ per year. The app instead divides by elapsed days / 365.25; its sample dates therefore produce a slightly different annual average. Neither average creates five additional claims on top of the period total.
The selected accounting reference is Standard T-VER-S-METH-13-01 v2: current tree stock minus baseline or last credited stock, minus prescribed project emissions and leakage. This method does not consider leakage, so that term is zero here. Its fire conditions, eligibility and small-project limit must be checked in the full document. Other activities and programme tiers can require different accounting. A loss stays negative; the software must not hide it behind a zero.
03 · What the satellite sees—and what it needs from the field
The JAXA vegetation page is a useful starting point. It provides routes to vegetation indices, leaf-area information and forest/non-forest products. These observations describe vegetation. They do not measure issued credits.
NDVI compares red and near-infrared reflectance. It can help describe greenness, but a greener pixel is not a universal quantity of stored carbon. Forest type, season, canopy structure and observation conditions affect interpretation. A model connecting imagery to biomass needs suitable measurements and validation.
| Source | Contribution to a pilot | Limit that travels with the data |
|---|---|---|
| JAXA PALSAR / PALSAR-2 | Radar predictors and forest screening; approximately 25 m mosaics | Preserve observation dates, masks and processing versions; check download registration and terms |
| Sentinel-2 | Optical predictors and cloud-screened change evidence | Compare usable observations with compatible seasons and processing |
| NASA GEDI L4A v3 | Footprint estimates of aboveground biomass density, prediction errors and quality information | Samples are not a continuous parcel census or error-free field truth |
| Measured field plots | Local evidence for fitting and independently testing a model | Record sampling design, coordinates, dates, species/group and measurement quality |
The project workbench does not use these products: its numbers come only from the user's own measurements. The carbon map (section 06) does use published satellite products — ESA CCI Biomass and JAXA's forest map among them. It runs no model of its own: it re-grids, masks and converts those products, and its landscape figures never feed a project calculation. The street and imagery basemaps are navigation aids, not evidence.
04 · Give AI a job it can be tested on
The useful first AI task is specific: predict biomass for a defined forest type from dated observations, then compare those predictions with independent measurements. A language model can help explain a method or flag a missing field. It should not fill a missing biomass value with a plausible sentence.
- Match plot locations, survey dates and satellite observations
- Separate training plots from spatially independent test plots
- Compare a simple baseline with a candidate biomass model
- Test bias, prediction error and uncertainty on unseen plots
- Document valid scope and obtain required method approval
A tempting shortcut is to split neighboring pixels randomly between training and testing. The test can then reward familiarity with the same landscape. For this pilot, reserve spatially separated plots and inspect error by forest type and biomass range. Compare a simple regression with a candidate such as Random Forest before accepting more complexity. This is a proposed validation design, not a completed experiment.
Uncertainty must follow the calculation. A difference between two uncertain stock maps is itself uncertain. Shared model errors, plot sampling and spatial correlation affect how much confidence to place in the change. Reporting more decimal places does not resolve those errors. The current workbench explicitly exports uncertainty as unavailable; a validated interval remains a prerequisite for a defensible project assessment.
05 · Open data: open the file before believing the label
The research search for “ป่าไม้” in data.go.th on 25 September 2026 returned 570 unique dataset records and 2,111 resource records. These are catalogue counts. They include documents, duplicate-looking resources, file components and links; they are not 570 ready-to-use biomass datasets. Nine selected resource files were downloaded and inspected. The app currently ships 11 normalized province-year observations.
| Source inspected | What was actually found | Decision |
|---|---|---|
| Saraburi forest area | Seven annual observations, 2018–2024; 2024: 532,177.56 rai | Historical province context |
| Kanchanaburi forest area | Four years, 2021–2024; 2024: 7,478,170.33 rai | Historical province context; checked unit agreement |
| RFD forest cover 2019 | ZIP contained metadata only; separate geometry headers were probed | Full geometry not ingested; CRS is UTM 47N, requiring reprojection |
| DNP conservation-area carbon | Table labelled tCO₂eq without an explicit annual denominator | Do not label it yearly credits |
| Reserved-forest table | Inconsistent area units in an inspected row | Quarantined; no guessed correction |
The full research record, download manifest and normalized province data make these decisions inspectable. A catalogue's “modified” date is not automatically a measurement date. Conflicting or restrictive licences require clarification before reuse.
The RFD dashboard: a useful lead with a visible discrepancy
The Royal Forest Department dashboard, inspected on 25 September 2026, displayed 83,290 plantation registrants, 83,681 plots, 1,447,111 rai and 139,013,341 trees. Its regional registration breakdown summed to 83,217 registrants, a difference of 73. No explicit update date explaining this difference was found during inspection. These are separate observed views; neither has been silently corrected.
The northern drill-down returned 9,480 registrants in Nan and 9,538 in Uttaradit. These counts can inform a discussion about where to seek pilot partners. They cannot establish current living biomass. Public endpoints returned HTML and chart configuration without login; no documented API contract was established. These observations are a dated research snapshot, not a live integration or calculator input.
06 · Absorption and emission from space
The workbench answers a project question: how much has this parcel's measured carbon changed? The carbon map answers a landscape question. How much carbon do a province's forests hold? How much do they take up and release each year? What else is emitted in the same place? It uses published satellite-derived products and runs no model of its own: it re-grids, masks and converts those products, as described below. Every figure in it is a screening estimate, never a credit, and never an input to the project workbench.
- 100 m satellite biomass (ESA CCI 2020) and the JAXA forest map (FNF 2020)
- Each pixel counted once: one province, one 2.8 km grid cell
- Forest carbon stock, with a 95% range
- Beside it, never added: GFW forest flux, GFED fire, ODIAC fossil CO₂
- Cross-checked against Climate TRACE and Thailand's own inventory (BTR1)
Four quantities, four datasets
| Quantity | What the map shows | Dataset | Period | Resolution |
|---|---|---|---|---|
| Carbon stock | Carbon held in forest trees, tCO₂e | ESA CCI Biomass v7.0 aboveground biomass, masked with JAXA PALSAR-2 FNF v2.1.0 | 2020 | 100 m |
| Forest flux | Gross removals, gross emissions and their net, tCO₂e per year | GFW forest carbon flux v1.4.3 (Harris et al. 2021; Gibbs et al. 2025) | Average of 2001–2025 | 30 m model, summarised by province |
| Fire | CO₂ from all landscape fire, with the share by land type and month | GFED5.1 | Mean of 2013–2022 | 0.25° (about 28 km) |
| Fossil CO₂ | Energy, industry and transport emissions | ODIAC2025 | 2024 | 1 km |
Cross-checks: Climate TRACE API v7 forest subsectors by province for 2024, and Thailand's First Biennial Transparency Report (BTR1) for the nation in 2022. Province boundaries are the Royal Thai Survey Department's, published by OCHA/HDX (COD-AB v01).
Where JAXA fits
JAXA's vegetation page offers NDVI, leaf area and a forest/non-forest map. None of these is a carbon stock. The carbon map uses JAXA's 2020 forest/non-forest map in three ways. It is the visible "JAXA forest map (FNF 2020)" layer. It decides which part of each biomass pixel counts as forest. Its land classes also weight how coarse fire and fossil data are spread over land. Both FNF forest classes count: canopy of 90% or more, and canopy between 10% and 90%.
FNF forest is not the Royal Forest Department's forest. FNF maps 44.7% of Thailand as forest in 2020. The Royal Forest Department reports 31.64% (102,353,484.76 rai) for the same year. A radar forest mask sees tree canopy. It does not know whether the trees are natural forest, plantation or a tree crop. Read "forest" on this map as "tree canopy seen by radar", not as a legal or administrative forest.
How a number is computed
One pixel, counted once. Every 100 m biomass pixel is assigned by its centre to at most one province and exactly one 2.8 km grid cell. Provinces, grid cells and the national total are therefore sums of the same pixels. Automated tests check this for every quantity. Thailand's land area computed pixel by pixel is 515,415 km². That matches the boundary file's own attribute (515,416 km²) and is within 0.45% of the official 513,120 km².
From biomass to CO₂e. Stock (tCO₂e) = aboveground biomass (t) × (1 + 0.27) × 0.47 × 44/12. That is 2.1886 tCO₂e per tonne of aboveground biomass. These are the general-tree values of TGO's tree tool, the same ones the workbench uses. IPCC 2019 root-to-shoot ratios for Asian tropical natural forests range from about 0.21 to 0.44 by forest type and biomass class (2019 Refinement, Vol. 4, Ch. 4, Table 4.4). Using that range instead would move total biomass by about −5% to +13%.
Forest share of a pixel. ESA CCI biomass is a mean over the whole pixel, forest or not. Each pixel's biomass is multiplied by the fraction of the pixel that FNF classes as forest. This assumes biomass is spread evenly within the pixel. It also keeps forest plus non-forest equal to the total, so nothing is created or lost.
Coarse data. Fire (0.25°) and fossil CO₂ (1 km) are spread over the 100 m land pixels in each coarse cell in proportion to land area. A coarse cell with no land in the JAXA map, such as a coastal sliver, falls back to plain area, so no emission is lost in the allocation step. Emissions allocated outside Thai province boundaries, such as offshore or across a border, are excluded by design. The Thai fossil total from this allocation differs by 0.3% from a crude alternative that assigns whole 1 km cells by their centre.
Drawn boxes. A box is summed from 2.8 km cells, each weighted by the share of its area on the sphere that falls inside the box. Values are assumed to be spread evenly within a cell. The sum counts Thai land only; parts of a box outside Thailand add nothing. A project boundary imported in the workbench is summed with 16 sample points per cell. In practice box figures therefore have about 2.8 km resolution, not 100 m. A figure is greyed out when the box's shorter side is narrower than the dataset's cell: 2.8 km for stock, 28 km for fire, 1 km for fossil CO₂.
Uncertainty, stated as a range rather than a decimal
ESA CCI publishes a standard deviation for every 100 m pixel. How those errors add up over a province depends on how much neighbouring pixels err together, which a single map cannot tell. The carbon map shows three 95% ranges for the random part of the map error:
| Range | Assumption | Thailand | Chiang Mai | Samut Songkhram |
|---|---|---|---|---|
| Floor | every pixel errs independently | ±0.03% | ±0.10% | ±1.5% |
| Central | errors fully correlated within 5.6 km blocks, independent between blocks | ±1.4% | ±4.7% | ±43% |
| Ceiling | every pixel errs in the same direction | ±110% | ±116% | ±121% |
The central range is tied to the data producer's own error model. ESA's product guide states that its aggregated maps (1, 10, 25 and 50 km) carry a standard error with a variance term and a covariance term, the spatial correlation of errors having been estimated from airborne LiDAR (CCI Biomass Product User Guide v6, §5). The pipeline recomputes, for every fully mapped 10, 25 and 50 km cell in the processing window, the error that the block model gives from the 100 m pixel errors and compares it with the error ESA published for that cell in 2020. With 5.6 km blocks, the model's error is 1.47 times ESA's at 10 km (median of 2,068 cells), 1.23 times at 25 km (197 cells) and 1.32 times at 50 km (18 cells): consistent with ESA's LiDAR-based estimate and on the cautious side at every scale checked. 5.6 km is the smallest block that lines up with the grid the browser uses for drawn boxes. Two limits apply. ESA's aggregates come from a slightly different processing run (BIOMASAR v202509) than the 100 m tiles (v202510); their means are 5–16% below means recomputed from the tiles, so this is consistency, not exact reproduction. And provinces and the nation are larger than 50 km: at those scales the model assumes errors are independent beyond one block, which does not cover a shared bias across a whole region. The ratios are recomputed on every build and stored in the ledger manifest.
All three ranges describe random error only. They exclude systematic map bias, which is usually the larger problem: global biomass maps tend to overestimate low biomass and underestimate high biomass (Araza et al. 2022), and a study of New York State parcels found that spatially correlated residual error dominated (Johnson et al.). The CCI Biomass fact sheet (written for v5; the map uses v7.0) advises checking regional totals against a national forest inventory or field plots, and says estimates for individual full-resolution pixels should not be used on their own (CCI Biomass v5 fact sheet). That check follows, in "Checked against Thailand's forest inventory": the national totals differ, without isolating map bias. GFW's province summaries carry only partial variance components, not a complete flux uncertainty, and the map does not use them. Its global estimate of removals for 2001–2023 is −14.5 ± 7.7 GtCO₂ per year (Gibbs et al. 2025). GFED and ODIAC publish no pixel uncertainty. The ODIAC spatial pattern is itself a model: national totals spread by night lights and point sources.
Checked against Thailand's forest inventory
A satellite map should be checked against field measurements before its totals are trusted. Thailand's forest reference level submitted to the UNFCCC (FREL/FRL, modified July 2021) publishes what the national forest inventory found: mean aboveground biomass per forest type from cycle 3 plots measured 2013–2018 (reference year 2017; Table 13), and the area of each forest type in 2016 (Table 6). The pipeline compares the two at national scale, with a nominal 2017 reference but differing measurement years and forest populations, rather than matched plots against pixels (Réjou-Méchain et al. 2019). Script: scripts/ingest/nfi_check.py; result: nfi-check.json.
| National forest inventory (FREL) | ESA CCI 2017 over JAXA FNF 2017 forest | |
|---|---|---|
| Forest area | 17.2 Mha ± 0.7 | 23.8 Mha |
| Mean aboveground biomass | 90.5 ± 5.0 t/ha | 165.0 t/ha |
| Total aboveground biomass | 1.56 ± 0.11 Gt | 3.94 Gt |
| Biomass carbon stock (above- and below-ground) | 3.48 ± 0.25 Gt CO₂e (FREL root:shoot by type) | — |
The two forest definitions differ, and that explains part of the gap. The inventory's forest excludes plantations other than teak; radar counts any tree canopy of at least 10% over at least 0.5 ha, including rubber and orchards. Treating inventory forest as a subset of radar forest allows a conditional bound (the figures below assume full nesting; radar misses some sparse dry dipterocarp forest, and inventory forest outside radar forest would lower them). If the map were unbiased on inventory forest, the 6.6 Mha of extra tree cover would have to hold the rest of the map's biomass — an average of 359 t/ha, more than two and a half times the inventory's evergreen forest (136 t/ha). This raises a plausibility question, not a measurement of extra-cover biomass. Under the hypothetical 0–200 t/ha range on the extra tree cover, the map would read 1.7 to 2.5 times the inventory on inventory forest.
In a small validation sample, the FREL tested its Thai allometric equations against 60 felled trees and found they underestimate tree biomass: −13.6% for tropical evergreen, −25.2% for mixed deciduous (Table 10). Applying those sample discrepancies as a national sensitivity scenario raises it to 112.1 ± 6.0 t/ha and 4.28 ± 0.30 Gt CO₂e. Under the same nesting assumption — the extra tree cover would need 303 t/ha against a corrected evergreen mean of 158 — and the conditional map-to-inventory ratio is 1.35 to 2.0 times the inventory. Sixty trees in three parks is a small sample, so this correction is shown as a sensitivity, not applied.
The discrepancy raises concern about possible map overestimation, but differing populations, masks, dates and allometry prevent an identified national bias or a test of the map interval's coverage. Araza et al. (2022) provides broader evidence of biomass-dependent errors, not a Thai correction factor. ESA values and the inventory's 3.48 Gt remain separately labelled. Provinces and boxes are not rescaled: a national ratio across unmatched definitions cannot calibrate parcel biomass. A forest-type comparison was also tried and rejected: the Copernicus LC100 2017 forest-type layer labels 97% of Thai forest evergreen, against about 35% in the inventory, so its strata cannot be matched to the inventory's.
The inventory has its own limits: plot sampling, trees only (saplings and bamboo sit in smaller sub-plots), the equation bias above, and different plot and map years. It is still the nationally designed, field-measured reference available to this research, and the one Thailand reports to the UNFCCC.
Why these figures are never added together
- GFW forest emissions already include forest loss caused by fire. GFED fire in forest classes, especially its "deforestation" class, may describe some of the same events. They are marked and never added.
- GFED counts all landscape fire. Its land types come from its own land-cover map. In Thailand 79% of fire carbon falls in its savanna, shrub and grass classes, and only 9% in cropland; in Chiang Mai, where JAXA maps 80% of the land as forest, the savanna group is 90%. Much of this is deciduous forest by Thai definitions, and Thailand's inventory reports wildfire carbon losses on forest land. IPCC practice treats CO₂ from cropland and grassland burning as balanced by regrowth; that assumption does not cover all of this fire. Fire CO₂ is shown as gross emission from burning, not as a net loss of stock.
- ODIAC excludes land use and biomass burning. Its scope complements the others, but its year and method differ. It sits beside the forest figures and is not netted against them.
- The only net shown is GFW's own: emissions minus removals within one model. A negative value means the forest is a net sink.
- Two stock years are never subtracted. ESA warns that differences between CCI years "may be affected by substantial biases" (fact sheet above). The Global Forest Observations Initiative rates change estimated from two biomass maps as research-level (GFOI 2025).
Aerosol is not carbon
The atmosphere layers answer a different question from the ledger:
- Aerosol optical depth measures particles: dust and smoke. It shows the burning season clearly and contains no CO₂.
- Carbon monoxide indicates combustion, but it is not CO₂.
- Column CO₂ (XCO₂) from OCO-2 is a concentration along a narrow orbit track, not an emission.
Directly, plume by plume, satellites can turn XCO₂ into an emission only for large, isolated sources. A study of power plants seen by OCO-2 and OCO-3 kept 106 usable cases out of about 23,000 candidate tracks (Atmospheric Chemistry and Physics, 2023). Atmospheric inversions using OCO-2 estimate coarse national and regional net fluxes (Byrne et al. 2023), not provincial totals. For this reason the atmosphere layers (NASA GIBS) are pictures with labels and never numbers.
Two national accounts, side by side
| Account | Removals | Emissions | Net | Scope |
|---|---|---|---|---|
| GFW, average 2001–2025 | 92.9 Mt/yr | 71.7 Mt CO₂e/yr | −21.2 Mt CO₂e/yr | Satellite-mapped forest with >30% tree cover in 2000, or later gain; stand-replacing loss |
| BTR1 2022, forest land remaining forest | 49.0 Mt | 19.7 Mt | −29.3 Mt | Managed land by national definitions |
| BTR1 2022, land converted to cropland | — | 12.5 Mt | +12.5 Mt | Conversion to cropland |
| BTR1 2022, whole LULUCF sector | 156.8 Mt | 48.6 Mt | −107.9 Mt | Includes cropland remaining cropland, −91.5 Mt |
Sources: GFW row, sum of the 77 province summaries divided by 25 (equal to GFW's own country table); GFW emissions include methane and nitrous oxide. BTR1 rows, Table 2-184, page 2-241, million tonnes; removals and emissions are CO₂, and the sector net also includes 0.27 Mt of methane and nitrous oxide from biomass burning. Most of Thailand's reported land sink sits in cropland remaining cropland, not forest. A satellite forest model and a national inventory also define "forest" and "anthropogenic" differently. Global bookkeeping models and national inventories differ by about 6.7 GtCO₂ per year for similar definitional reasons (Grassi et al. 2023). The carbon map shows both and chooses neither.
Tree cover lost, year by year
The flux figures above are 25-year totals. What a province usually asks is different: are we losing forest, how fast, and why? GFW publishes the same flux model year by year (carbonflux_adm1_change v20260327), with the same filter the ledger uses (tree cover ≥ 30% in 2000, inside the model extent). scripts/ingest/build_loss.py cooks it into one series per province and for Thailand, shown under the carbon figures when a province or the whole country is selected.
The first split matters most. Tree cover loss is not deforestation: rubber, eucalyptus and oil palm are cut and replanted, and the loss map counts that harvest. GFW's plantation map separates it. Of the 2.80 million ha of tree cover lost in 2001–2025, 0.99 million ha fell inside mapped plantations and 1.81 million ha outside them. The rest of the series is built on the loss outside plantations:
| Quantity | Thailand, 2001–2025 | Source field |
|---|---|---|
| Loss outside plantations | 1,812,331 ha | gfw_plantation_flux_model__type = Not applicable |
| … in primary forest (2001) | 116,033 ha | is__umd_regional_primary_forest_2001 |
| … in a protected area | 226,953 ha | wdpa_protected_areas__iucn_cat (any category) |
| Loss inside plantations | 990,377 ha | other plantation types |
| Main driver outside plantations | Permanent agriculture, 80% | WRI/Google dominant driver, one class per 1 km cell |
Three checks run on every build and in tests/loss.test.mjs: outside + inside plantations equals all loss in every province and year; the provinces add up to Thailand; and the 25-year emissions from the yearly table equal the summary table the ledger already ships, within 0.5%. Two limits stay visible beside the chart. The map records loss and not regrowth, so these are gross figures. And a driver is the dominant one in a 1 km cell, not a cause traced for each hectare. A drawn box has no yearly series, because GFW publishes it by province.
The ranking and map layer divide the 2021–2025 average by each province's tree cover outside plantations in 2000 (umd_tree_cover_extent_2000__ha, same filter), so a large province does not top the list by size alone. Thailand's rate is 0.43% a year (73,857 ha a year, against 100,635 ha in 2016–2020). The ten highest are all in the south or peninsula, led by Krabi (1.84%), Songkhla (1.58%) and Chumphon (1.37%), and in nine of the ten the main driver is permanent agriculture (79–98% of the loss); Phuket is the exception, with settlements and infrastructure at 52%. Treat that with care. GFW's plantation map can miss smallholder rubber and oil palm, so part of this "outside plantations" loss may be tree crops being cut and replanted. The denominator is the year 2000 and does not shrink as forest goes, so the rate is a screening comparison between provinces, not a forest-loss statistic. The two halves of the denominator rebuild the extent the ledger already ships, within 0.5% in every province. public/data/gfw/loss-years.csv holds every province-year with its source in each row.
Biomass year by year, and what can be said about change
The stock figures above are for 2020. ESA CCI Biomass v7.0 also publishes a map for every year from 2015 to 2024, and scripts/ingest/build_stock_years.py sums each one over all land in every province, with no forest mask, so a cleared forest shows as a fall. Thailand's aboveground biomass runs from 4,361 Mt in 2015 to 4,372 Mt in 2024, staying between 4,294 and 4,408 Mt. The 2020 value equals the ledger in every province.
The page converts it to tCO₂e with the same factor as the stock figures, roots included. Those yearly numbers are not a trend, so the site shows their range and a table rather than a chart of them. ESA's Product User Guide v7 (§3) says fluctuations from year to year are expected because each year uses different radar observations, and (§4) strongly advises reading any biomass difference through its quality flag, calling change maps research products. So change is reported only through ESA's classes: a pixel "reliably" fell or rose when its two 1-SD ranges do not overlap, "possibly" when they partly do, and otherwise shows no reliable change. A rise faster than 10 Mg/ha a year is also treated as no reliable change. The flags use ESA's own create_change_maps.py logic on 2017 and 2024; the window starts in 2017 because the guide notes thinner Sentinel-1 coverage before spring of that year.
Every build checks the flags against the one annual product ESA publishes, 2019–2020, on Thai land pixels: agreement is 99.9996% overall and 99.996% on changed pixels, and the build fails below 99.5% and 98%. Between 2017 and 2024, of the land holding biomass, 6.8% reliably fell, 1.7% possibly fell, 76.7% shows no reliable change, 6.4% possibly rose and 8.3% reliably rose. These are shares of 100 m pixels. They are not hectares of deforestation or planting, and they should not be added to or compared with the GFW loss figures above: the two come from different sensors and definitions.
Checks performed
Run on 26 September 2026:
- Conservation. Provinces, grid cells and a box covering Thailand all reproduce the national total for every quantity. Split boxes add up to the whole box.
- Boundary crosswalk. All 77 COD-AB province names match Climate TRACE's GADM names one to one. GFW rows are joined by the same GADM numbers, and GFW's province areas agree with COD-AB within 6.7%, which confirms the numbering.
- Fossil CO₂. ODIAC's 2024 total for Thailand is 290.0 Mt. BTR1 reports 271.1 Mt of CO₂ excluding land use for 2022 (Table 2-3), of which energy is 241.3 Mt and industrial processes 28.6 Mt. The scopes differ (ODIAC covers fossil combustion, cement and flaring), the years differ, and ODIAC projects recent years from energy statistics.
- Fire season. 83% of fire carbon falls in February–April, and March alone is 44%. This matches the northern burning season.
- Chiang Mai. GFED fire CO₂ is 12.1 Mt per year (2013–2022, all land types). Climate TRACE forest-land fires are 6.3 MtCO₂e (2024, forest only). The scopes differ; the order of magnitude agrees.
- Provenance. Every source file's URL, size, SHA-256 and retrieval date is in the ledger manifest. The processing code is
scripts/ingest/build_ledger.py.
What this map cannot tell you
- Credits, eligibility or additionality. A satellite removal figure has no baseline, no leakage deduction, no permanence buffer and no independent verification. See the ICVCM Core Carbon Principles.
- An approved method. T-VER remote-sensing models need TGO approval. These products have none for project use.
- Current conditions. Stock is for 2020, forest flux is a 2001–2025 average, fire is 2013–2022 and fossil CO₂ is 2024.
- Flux inside a drawn box. GFW's 30 m grids require an API key and are not yet ingested. The map says so instead of showing zero.
07 · Can open data become a carbon credit?
Short answer: no. Open and public data can screen a candidate, supply dated context, and flag what still needs measuring — but no satellite, catalogue or model output in this system is a credit, and none becomes one by arithmetic. A credit is minted outside this system, by people and a registry, after three gates that open data cannot pass on its own.
The three quantities from section 01 still govern everything below: carbon stock, monitoring-period change, and issued credits stay separate. Open data speaks fluently about the first, approximately about the second at landscape scale, and not at all about the third.
Three gates no satellite passes
A credit needs three things that are not pixels. First, rights and eligibility: who holds the land, whether the activity is additional to the baseline, and whether the same carbon has been claimed elsewhere. A polygon proves none of this. Second, an approved method with a baseline: T-VER-S-METH-13-01 v2 (or the method that fits the activity) names the pools, the equation CSEQ = CTT(t) − CTT(i) − PE − GHG_LEAK, the fire conditions (burned area above 5% with canopy fire causing tree death), and the small-project screen of 16,000 tCO₂e per year. An unapproved model — however accurate — is not a method. Third, independent validation and a registry: a second qualified party reproduces the result, the programme approves, and units are recorded. This pilot connects to no registry and runs no approved model; it says so on every screen.
Lane 1 · Open data — screening and context
- ESA CCI Biomass v7.0 (2020, 100 m) → stock context for a candidate area
- JAXA FNF v2.1.0 (2020, 25 m) → forest mask and visible change screening
- GFW flux v1.4.3 (2001–2025 average, province) → removals and emissions context, net only
- GFED5.1 (2013–2022, 0.25°) → dated fire evidence by month and land type
- ODIAC2025 (2024, 1 km) → fossil context, shown beside — never netted
- COD-AB v01 (valid 2022-01-22) → province boundaries for orientation
- Climate TRACE API v7 (2024) and BTR1 (2022) → independent cross-checks
This lane never mints a credit. Its job is to say where to look and what to verify.
Lane 2 · Field and approved method — the only path to a credit number
- Versioned boundary plus land rights → the calculation area becomes a project
- Measured plots at two comparable dates → dry biomass both sides of the period
- T-VER-S-METH-13-01 v2 arithmetic → CSEQ minus prescribed fire emissions
- Stated uncertainty and exclusions → the result travels with its limits
The workbench lives here: user-supplied measurements in, reproducible arithmetic out.
Lane 3 · Registry — external to this system
- Programme approval → eligibility, baseline and monitoring plan accepted
- Issuance → units recorded; open data never appears in this lane
Dashed because it happens elsewhere. No integration is claimed.
The pipeline, with open data in its place
- Open data screens candidates: FNF mask, CCI v7.0 stock context, GFW v1.4.3 flux context
- Gate A: rights, eligibility and baseline decided by people and documents
- Field plots at two comparable dates under T-VER-S-METH-13-01 v2
- CSEQ minus prescribed fire emissions; uncertainty travels with the result
- Gate B: independent validation reproduces the calculation
- Registry issuance is external; open data never appears there
What each open dataset can and cannot prove
| Credit ingredient | Open-data support (version, period) | What open data can never supply |
|---|---|---|
| Project boundary and rights | COD-AB v01 boundaries (valid 2022-01-22) for orientation; data.go.th community-forest rows as partner leads | Tenure, consent, additionality, proof against double claiming |
| Stock context | ESA CCI Biomass v7.0 (2020, 100 m) masked by JAXA FNF v2.1.0 (2020, 25 m) | Parcel stock at credit dates; approved-method status |
| Flux context | GFW flux v1.4.3 (2001–2025 average, province) | Baseline, leakage, permanence buffer, verification |
| Fire deduction evidence | GFED5.1 (2013–2022, 0.25°) by month and group | Whether canopy fire killed trees on the parcel — that needs the field |
| Fossil context, never netted | ODIAC2025 (2024, 1 km) | Anything about the forest credit |
| Independent cross-checks | Climate TRACE API v7 (2024, province); BTR1 Table 2-184 (2022, nation) | A second opinion is not validation |
A walk-through with teaching numbers
Reuse the section 02 teaching case — dry aboveground biomass rising from 1,000 to 1,100 tonnes — and watch each number change hands:
- Screening: FNF v2.1.0 mask plus CCI v7.0 stock context for the candidate area
- Field evidence: dry aboveground biomass 1,000 to 1,100 tonnes (teaching numbers, not a measured forest)
- CSEQ arithmetic: 100 × 1.27 × 0.47 × 44/12 = 218.8633 tCO₂ before deductions
- Deductions and screens: fire over 5% with canopy death, 16,000 tCO₂e per year limit, stated uncertainty
- Validation and registry decide; the screening estimate is never the claim
The screening numbers and the credit number meet only at Gate B, where a validator reproduces the field arithmetic — never by copying a satellite total into the claim. GFW's own net (−21.2 MtCO₂e per year for Thailand, 2001–2025) stays a landscape context beside the claim; GFED fire stays gross burning, not net loss; ODIAC fossil CO₂ stays beside the forest figures, never netted. The workbench enforces the same separation: its numbers come only from user-supplied measurements, and landscape figures never feed it.
What would have to change — and what this pilot already does
For an open-data pipeline to end in a real credit, three external things must exist: a remote-sensing model with TGO approval for the activity (the four approved platforms announced 13 June 2025 hold their own approvals, which do not transfer to this application); parcel-scale flux access without a key barrier (GFW's 30 m grids need an API key this pilot does not hold); and a registry integration with independent verification (this pilot has neither and claims neither). Until then, the honest system is the one drawn above: open data screens and contextualises, fieldwork plus an approved method produces the number, people and the registry decide. This pilot already runs the middle of that drawing — reproducible arithmetic with all inputs, dates, versions and limits attached — so that when the gates open, the evidence is ready to walk through them.
08 · The first pilot should earn the next one
Start with one project whose boundary, rights, methodology and field records can be checked. Agree on the decision first: screening a candidate, estimating stock, or preparing monitoring evidence. Each requires a different level of proof.
- One project: boundary, rights, applicable methodology
- Baseline and repeat field evidence with dates and units
- Reproduce the calculation and challenge the assumptions
- Independent validation and uncertainty assessment
- Review with the relevant programme before expanding
A useful pilot pack includes a versioned boundary, the project's registration details where applicable, sampling design, plot measurements at comparable dates, disturbance records, and permission to use the data. If an approved remote-sensing provider is involved, obtain its output definitions, approved scope and uncertainty documentation. An approval held by another platform does not transfer to this application.
The pilot succeeds when another qualified person can reproduce the result, explain its limits and identify the measurements that would change the conclusion. That is a harder target than making the map look convincing. It is also a target worth building for.
09 · The person behind the work
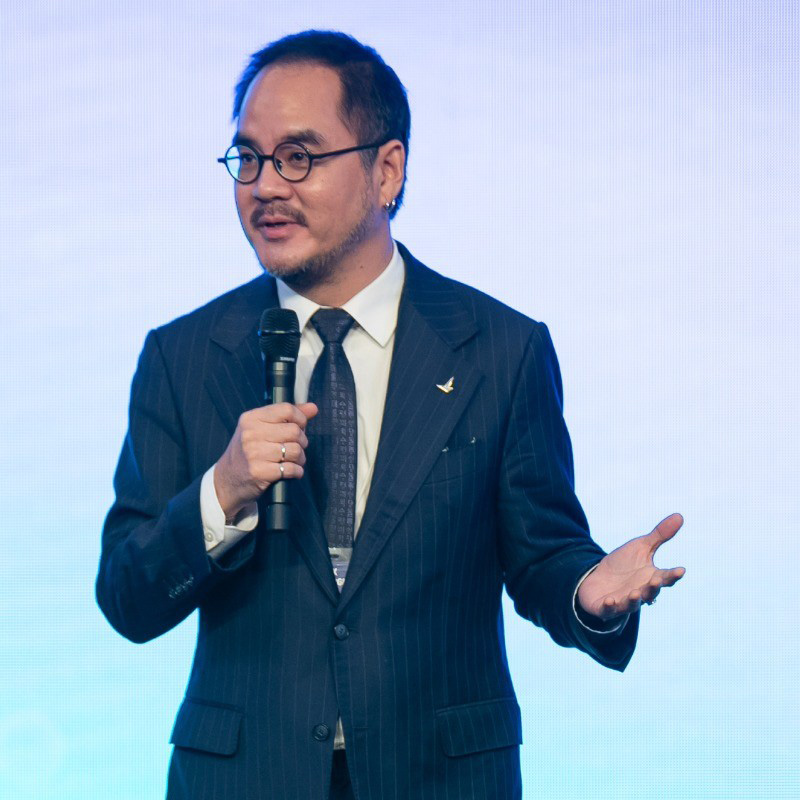
Dr Non Arkaraprasertkul
Architect, anthropologist and civic-systems builder. His public profile describes architectural training at MIT, anthropology at Harvard, and work in smart-city promotion at Thailand's Digital Economy Promotion Agency (depa).
The connection to forest carbon is a design question: how can complicated evidence become usable by people making decisions? This project applies that question to boundaries, measurements and the public record behind each estimate.
Portrait source: RMIT Vietnam's profile. Biography checked against that page and the personal website on 25 September 2026. Institutional affiliations provide background; this independent pilot does not claim institutional endorsement. No personal quotation or fieldwork story has been invented for this page.
10 · Keep the evidence within reach
The Thai guide and English guide cover actual use, formulas, file formats and deployment. The source catalogue records the supplied references. Code and tests are public, together with the original research audit. Official documents linked above govern their own methods; this page is an explanation, not a replacement.
Open the workbench, try the clearly labelled synthetic example, and follow a number back to its inputs. Then ask what evidence would be needed to replace that example with a real forest. That is where this work becomes useful.
11 · TGO's T-VER registry — context, not an input
Thailand Greenhouse Gas Management Organization (TGO) is a public organisation under the Ministry of Natural Resources and Environment, established by royal decree in 2007 (amended 2019 and 2025). It runs the Thailand Voluntary Emission Reduction Program (T-VER) and its registry, licenses carbon labels, and registers the external bodies that validate and verify projects. The national greenhouse-gas inventory is now reported by the Department of Climate Change and Environment (DCCE); Thailand's BTR1, cited in section 06, is a DCCE publication.
On 13 June 2025 TGO presented four remote-sensing platforms that had met its assessment criteria for estimating forest carbon sequestration in T-VER forestry projects: GISTDA Carbon Atlas, THAICOM CarbonWatch, SCGC CERT+ and Varuna Smart Forest (PTT group) (TGO news). The release says they reduce time and cost; it gives no percentage, and it does not describe them as verification. External bodies still verify. Each recognition belongs to that platform. This application is an independent, open screening tool and claims no TGO recognition.
The TGO T-VER database publishes its full project list without login. A snapshot taken on 28 September 2026, limited to the forestry and agriculture sector (FOR&AGR), shows:
- 257 registered projects, with a combined ex-ante expectation of 2,194,333 tCO₂e per year (median project 771 tCO₂e/yr)
- 31 projects have had credits issued, 733,914 tCO₂e in total
- 75 projects include ป่าชุมชน (community forest) in the registered name. The extract does not record the legal instrument behind them.
- 32 projects mention mangrove (ชายเลน) in the name or methodology. The mangrove methodology tag is on 3; the rest use a general forestry method. The Department of Marine and Coastal Resources is the developer on 30 of the 32.
- 246 projects are Standard T-VER and 11 are Premium T-VER. Status: 253 active, 2 ended, 1 in revalidation, 1 withdrawn.
Few issuances so far — mostly because most projects are new
31 of 257 projects (12.1%) have received credits. Read by the year of registration, the figure is a timing effect before it is anything else:
| Registered | Projects | With credits issued | Share |
|---|---|---|---|
| 2021 or earlier | 27 | 15 | 56% |
| 2022–2023 | 30 | 12 | 40% |
| 2024–2026 | 200 | 4 | 2% |
Four in five projects were registered in 2024–2026. Most have not yet reached the end of a first monitoring period, so no credit could have been issued. This snapshot cannot tell whether verification cost also holds projects back: it contains no verification fees, and the page does not estimate them.
What the OTC tape in the snapshot shows: forestry and agriculture trades total 379,304 tCO₂e at a volume-weighted average of ฿416/tCO₂e. Yearly averages run from ฿279 in 2023 (308,030 tCO₂e, the largest year) to ฿2,000 in 2022 (1,270 tCO₂e). There is no stable price band in these data.
Standard and Premium T-VER, as registered
| Standard T-VER | Premium T-VER | |
|---|---|---|
| Forestry & agriculture methodologies in use (codes as printed) | S-METH-13-01 to 13-06 and their predecessors (METH-FOR-01…04, METH-AGR-01/02) | P-METH-13-01 (A/R), 13-02 (mangrove), 13-03 (REDD+), 13-05 (IFM), 13-08 (rice) |
| Crediting periods registered in this snapshot | 10 yr (180 projects), 7 yr (35), 20 yr (25), others 9–23 yr (6) | 5 yr (3), 15 yr (5), 20 yr (2), 39 yr (1) |
| Projects | 246 (95.7%) | 11 (4.3%) |
| Earliest crediting start | September 2013 | July 2023 |
| International use | Domestic voluntary use | Premium credits are listed as CORSIA-eligible for the 2024–2026 phase; use under Article 6 needs a letter of authorization and a corresponding adjustment, which is not automatic |
The crediting periods are measured from each project's start and end dates in the registry, not taken from programme rules. Five Standard projects list a P-METH methodology code; the table keeps the codes as TGO prints them. TGO's Premium rules include a non-permanence buffer; its size is set by TGO's buffer tool and is not reproduced here. The small Premium count mostly reflects how new the programme is.
Double-counting screen at the boundary
TGO's listing and detail pages describe locations as text addresses. Where maps or coordinates exist, they sit inside each project's registration document (a PDF linked from the detail page), not in a machine-readable layer. Checking whether a new parcel overlaps a registered one therefore still needs those documents.
This workbench narrows the search when a boundary is imported:
- It tests the boundary against the official COD-AB province boundaries.
- It lists T-VER projects registered in those provinces, with developer, methodology family and crediting term.
- It shows their combined expected and issued tonnes. A multi-province project's full tonnage appears in every province it names, so these screen totals are not additive.
Sharing a province is not overlap, and it says nothing about additionality. It tells a developer which registration documents to open first.
The Climate Change Bill (status as of September 2026)
Cabinet approved a draft Climate Change Act in principle on 2 December 2025 and sent it to the Council of State (JETRO). Parliament held a public consultation on a bill from 25 May to 24 June 2026, and press coverage in July 2026 still described it as a draft. The drafts include mandatory reporting for large emitters, an emissions trading system and a carbon tax. ICAP reports that DCCE would establish the trading system's registry and that TGO-certified credits could cover a limited share of compliance obligations. Final text, timing and the registry arrangement remain open until enactment.
A reproducible fetch pipeline
scripts/ingest/tgo.py fetches the project list, each forestry project's detail page and the reported OTC trades:
- It uses
research/raw/tgo/as a local cache, so repeated runs do not re-download. - It records a SHA-256 fingerprint of the cached raw files in the output.
- It assigns a province automatically only when the address text contains จ. or จังหวัด, which avoids false matches on ordinary words that are also province names (เลย, แพร่, ตาก).
- Twelve other cases were reviewed by hand; each decision and its reason is in
scripts/ingest/tgo_province_overrides.json. - It stops if single-province, multi-province and unlocated totals do not add up to the national totals, or if any project's issuance records do not add up to its listed total.
The output, public/data/tgo/tver-forestry.json (about 390 KB), carries 257 projects tagged with 8 methodology families in use (A/R, large-scale A/R, REDD+, plantation, mangrove, IFM, agricultural land, perennial crops; the peat tag has no projects) and 31 issuance histories.
Why registry figures are context, never project carbon inputs
The registry data on the map describe institutions: where projects are registered, what they expect and what has been issued. Satellite stock (CCI Biomass v7.0, JAXA FNF v2.1.0) and forest flux (GFW v1.4.3) are never added to, subtracted from or divided by registry figures. They sit side by side, each with its source.
12 · What the registry says about itself — slices TGO does not aggregate for you
Pulling all 257 records turns TGO's flat listing into slices the public site does not aggregate. They appear in the T-VER block of the national map view, beside the project list and the OTC table. The figures below were computed from the snapshot data/tgo/tver-forestry.json (28 September 2026); the app computes the same slices from that file.
| Slice | What it says |
|---|---|
| Issuance by age | 31 of 257 projects (12.1%) have received credits: 56% of projects registered by 2021, 40% of 2022–23, 2% of 2024–26. The 226 without issuance carry an ex-ante expectation of 1,982,918 tCO₂e/yr. That expectation is not a removal and not a credit. |
| Methodology coverage | Family tags, not a partition: reg. 001 carries both A/R and REDD+, and 23 projects have no methodology text. Tags: A/R 110, REDD+ 69, perennial 30, agricultural land 10, plantation 8, A/R large 4, mangrove 3, IFM 1. Mangrove, plantation and IFM have no credits issued. The largest unissued group is A/R, 102 of 110. |
| Project size (TGO's label) | Micro 144, small 89, large 24. Of the micro projects, 45 include ป่าชุมชน in the name (31%). Of the large projects, 13 are perennial-crop projects, 10 of them by the Rubber Authority of Thailand. |
| Programme and form | Standard 246, Premium 11 · single or bundled 243, programme of activities 14. |
| Developers | By project count: Royal Forest Department 35, Department of Marine and Coastal Resources 27, BAAC 12, Rubber Authority of Thailand 10, Department of National Parks 9. By expected tCO₂e/yr: Rubber Authority 653,175, Royal Forest Department 458,576, DMCR 210,920. Names are kept as printed, so two spellings of one foundation stay separate. |
| Where | Ranked by expected tonnes of single-province projects: Nan, Chiang Rai, Surat Thani, Rayong and Chiang Mai hold 33.3% of national expected volume. Multi-province projects (52; 1,075,734 tCO₂e/yr) are outside this ranking. Single-province 199, multi-province 52, no province named 6. |
| Issuance timeline (tCO₂e) | 2016 1.5k, 2017 16, 2018 0.8k, 2022 5.6k, 2023 130k, 2024 424k, 2025 57k, 2026 115k to date. Of 2024, 419,513 tCO₂e (98.9%) is one REDD+ issuance: Doi Tung Development Project, Chiang Rai (reg. 077). |
| OTC trades (FOR&AGR) | Yearly average ฿279 (2023) to ฿2,000 (2022); yearly volume 16 tCO₂e (2021) to 308,030 tCO₂e (2023); volume-weighted average ฿416/tCO₂e. 2026 is year-to-date. |
Why this is useful to TGO without being an integration
The slices come from one static snapshot of TGO's public listing. They are not a registry connection, not a verification and not an audit. They are the same data, sliced:
- No login and no API key. The browser reads
data/tgo/tver-forestry.jsononce. - No server processing. Every aggregate runs in the browser.
- No silent drift.
tests/tgo.test.mjschecks that single-province, multi-province and unlocated projects reconcile with the national totals, that 31 projects have issuance, and that every issuance history sums to its project total. - Reproducible.
scripts/ingest/tgo.pyrebuilds the snapshot from the cached raw pages.
Further views TGO may want — retirements by project, vintages, corresponding-adjustment status — would need data the public listing does not carry. Views of what it does carry are small additions to the same snapshot.
13 · Why the name is คาร์บอนนะ
Brand update · 2 October 2026: the owner supplied the CT leaf identity now used in the header, browser icon and mobile web app. Character update · 4 November 2026: the six teaching poses are now Nong Non (น้องนนท์) — the initiator himself as a boy, drawn from his own childhood photographs. A person's own face is the one likeness this project can ship without borrowing one. The face keeps every property the section below cites: large head, large eyes, small body, square props, the same navy and the same two accents. The earlier round-creature exploration stays on disk under images/kabonna/.
The official product name is Carbona, or คาร์บอนนะ in Thai, from 21 October 2026. The name, the mark and the six poses are soft on purpose. Softness is how a person who is not a carbon accountant finds the tab, says the name, and stays. It is not how a tonne is calculated. The ledger, the sources and the uncertainty stay in the square record. The face never sits on a number.

The name is a hedge you can hear
คาร์บอนนะ combines the standard Thai spelling of carbon with the particle นะ. The ending softens an utterance; it does not establish the truth of a carbon claim. No official Japanese name is specified. The field this tool sits next to is full of acronyms: TGO, T-VER, CCI, GFW, ODIAC. A distinctive name can help someone find the tool (von Restorff, 1933); it cannot replace source evidence or verification.
The softness is also the claim the product is willing to make. An estimate is not a credit. A name that already sounds like it is checking with you — “carbon, yeah?” — is harder to mistake for a stamp.
Why a round face belongs in a square interface
Faces with a large head, large eyes and a small body are what Lorenz called the baby schema. Glocker and colleagues manipulated those features in infant photographs and found that they raised both rated cuteness and the reported wish to look after the infant (Glocker et al., 2009). Applying that to a drawn mascot is an extrapolation, not a result of the study. The hope is that a familiar face helps readers return to an explanation. That navigation benefit has not been tested here. Nittono and colleagues found that looking at cute images can make the next small task more careful, and can narrow attention (Nittono et al., 2012). That is a reason to hope someone looks closely. It is not a reason to believe the arithmetic got better. A face cannot check a tonne. The carefulness still has to be in the sources, the factors and the tests.
So the mascot is allowed to be round, and almost nothing else is. The map, the rules, the tables and the three props the character holds — the viewing square, the plot flag, the stop palm — stay square, in the same paper, navy and yellow as the rest of the screen. One leaf is forest green, from the stock map. The other is yellow, the only accent. Curves are the exception that makes the face work. They stop at the face.
Six poses, six jobs
The same character, so the face stays one memory. The pose changes, so the face can carry a job without being pasted onto a result.
 GreetOpen hands welcome the reader. Nong Non introduces the notebook; the CT leaf remains the product mark.
 LookA square, the drawn box and the satellite cell. Looking is not a verdict.
 BothA leaf in one hand, a plume in the other, with a gap. Absorption and emission are shown together and never added.
 MeasureA flag in a small square plot. Field evidence, not a guess from the portrait.
 WonderEyes up, mouth open. The uncertain part stays visible. Not knowing is a pose, not a hole to be filled with a zero.
 StopPalm forward. The cute layer ends before a credit. Issued units are not this character's job.
Greet is the only pose that keeps the product's name line live across both notebooks — the header itself has carried the owner's CT-leaf mark since 2 October, so the public face on screen is the leaf, not a boy. Look, Both, Measure and Wonder are the work: see the area, keep the two sides apart, ask for a plot, and leave the uncertainty on the screen. Stop is the limit of the whole idea. Cuteness that crosses into the credit line would spend the trust the baby schema borrowed. The boy can wave. He cannot certify.
Global data sources, cadence and fallback rules / แหล่งข้อมูลโลกและรอบการอัปเดต.
14 · Other systems, and whose methods this one uses
Forest-carbon estimation from space is a crowded field. The systems below were reviewed on 29 September 2026 from their own public pages. Where a system publishes no accuracy figure, the table says so rather than guessing one.
| System | Method, as published | Resolution | Open? | Accuracy it reports |
|---|---|---|---|---|
| GISTDA Carbon Atlas | ALOS-2, Sentinel-1/2, Landsat-8, GEDI forest height and SRTM terrain with AI/ML; over 1,000 field plots measured by terrestrial laser scanning | Not stated | Free viewer; model not published | "Verified accuracy", no figure given |
| THAICOM CarbonWatch | High-resolution imagery and AI | Not stated | Commercial | Not published on its technology page |
| SCGC CERT+ | Imagery to tree height and crown width, then biomass | Not stated | Commercial | Not published |
| Varuna Smart Forest (TGO announcement) | Satellite, drone and ground data with AI, as described by the company | Not stated | Commercial | Not published |
| CTrees AGB | Yearly aboveground biomass density with an uncertainty layer, 2000–2025 | 100 m | Open (CC BY 4.0) | Not stated on the dataset page |
| Kanop | Machine-learning biomass model from satellite imagery, checked against LiDAR-derived maps | 30 m | Commercial | Site level: RMSE 41.7 t DM/ha (27%), R² 0.73 over 110 sites; 30 m pixel level: RMSE 94.9 t DM/ha (vendor) |
| Sylvera | Ground, drone and airborne LiDAR chained to satellite models; annual since 2000 | 30 m | Commercial | "Project-area errors below 10% for projects over 400 ha" (vendor claim) |
| Chloris Geospatial | Yearly biomass stocks with per-pixel uncertainty | Not stated | Commercial | Says it is validated against NEON field plots, airborne LiDAR and GEDI; figures not on the page |
| Planet Forest Carbon Diligence | Canopy height and cover from airborne LiDAR, carbon from GEDI L4A footprints | 30 m | Commercial | Validation report exists; figures not extracted |
| Global Forest Watch flux | Activity data × emission and removal factors | ~30 m | Open | Global net −5.5 ± 8.1 GtCO₂e/yr (Gibbs et al. 2025) |
The four Thai platforms are the ones TGO recognised for T-VER forestry work in June 2025 (section 11). None publishes an accuracy figure that can be checked. The global vendors publish validation reports, mostly for their own models against LiDAR.
What คาร์บอนนะ does differently
Of the systems in this list, it is the one that publishes all of the following together for Thailand (Global Forest Watch also publishes open code for its flux model):
- Its whole method and code, including the offline pipeline, the fetch log with file hashes, and the tests.
- A conservation rule: provinces, drawn boxes and the national total are sums of the same 100 m pixels and are tested to agree.
- An uncertainty range calibrated to the data producer: the central random-error model was tuned against producer aggregates; median SD ratios are 1.23–1.47 across differing processing runs. This is a consistency diagnostic, not independent coverage validation (section 06).
- A check against Thailand's own forest inventory, across unmatched national forest populations, with published inventory uncertainty and an explicitly conditional allometric sensitivity (section 06).
- Registry context kept apart from estimates: TGO's registered and issued tonnes sit beside the satellite figures and are never added to them (sections 11–12).
It is also free and needs no account. It does not claim higher accuracy than the commercial systems, and it is not a replacement for a verified project method.
What the others do that this one does not yet
- Higher resolution and LiDAR-trained models (Sylvera, Kanop, Planet). The 100 m ESA map cannot see individual trees, and drawn boxes work at about 2.8 km.
- Annual time series (CTrees, Chloris, Sylvera). This map uses one stock year. CCI v7 has yearly maps and a change product with its own quality flag, which would allow change estimates without subtracting two maps naively.
- Field-calibrated models for Thai forest types (GISTDA). Here, Thai field data enter only as a national check, not as a calibration.
- More than one biomass map. Map-to-map disagreement is often larger than any single map's stated error (Araza et al. 2023). Adding CTrees AGB (CC BY 4.0, yearly, with uncertainty) as a second map would show that spread by province.
- Sample-based province estimates from GEDI lidar footprints combined with the map through small-area estimation (Ståhl et al. 2016). This needs an Earthdata account.
These are the next improvements, in roughly that order of value for the effort.
Methods used here, and whom they come from
| Step | Method | Credit |
|---|---|---|
| Biomass per 100 m pixel, with error | ESA CCI Biomass v7.0 | Santoro and Cartus, ESA Climate Change Initiative (DOI 10.5285/6429d1aafe1e43b9b414e4a5a7f8b903) |
| Forest fraction of each pixel | JAXA ALOS-2 PALSAR-2 forest/non-forest map | JAXA EORC |
| Biomass to CO₂e | AGB × (1 + R) × CF × 44/12 | IPCC 2006 Vol. 4; TGO T-VER-S-TOOL-01-01 v2 factors |
| Error aggregation with spatial correlation | Variance plus covariance, correlation from airborne LiDAR; approximated here with a block model tuned to producer aggregates, not independently validated | ESA CCI Biomass PUG v6 §5; propagation along the tree–plot–pixel chain after Réjou-Méchain et al. 2019; spatial aggregation of map uncertainty after Wadoux and Heuvelink 2023 |
| National map versus inventory discrepancy | Unmatched national populations; published inventory uncertainty and conditional scenarios | Réjou-Méchain et al. 2019; Araza et al. 2022; Thailand FREL/FRL 2021 |
| Rejected forest-type matching experiment | Copernicus LC100 v3.0.1, 2017; 97% evergreen versus ~35% in NFI, not used for matched validation | Buchhorn et al., Copernicus Global Land Service (CC BY 4.0) |
| Forest carbon flux | Gain–loss model with 30 m activity data | Harris et al. 2021; Gibbs et al. 2025 |
| Fire emissions | GFED5.1 | van der Werf, Chen and colleagues |
| Fossil CO₂ | ODIAC2025 | Oda and Maksyutov, NIES |
| Double-counting screen | Province match from TGO addresses | TGO public T-VER database |
15 · What can the open data actually identify?
The research question and the verdict
For each target quantity in Carbona, do the available observations identify it at the requested spatial and temporal support, and what independent evidence would make the inference defensible? “PhD-level” here means a falsifiable question, explicit assumptions, reproducible experiments and attention to contrary evidence. It does not mean a degree, peer review, official verification or a completed field campaign.
Our conclusion is useful precisely because it is bounded: the deployed products support a model-conditioned landscape account and reproducible calculations from user-supplied measurements. They do not independently identify current parcel biomass, project-attributable mitigation, organizational emissions or credit entitlement. More layers can improve an estimate; they cannot remove a missing counterfactual or establish rights.
1. What the system tries to know
An estimand is the quantity we intend to estimate, with its population, boundary, pools and date. Let θ be that quantity, y the sensor observation, and h the process linking them: y = h(θ, environment, sensor) + error. If two plausible states of the world produce the same y but different θ, the available observations alone do not identify θ. A fitted model supplies assumptions and calibration; it is not a direct carbon measurement.
GFOI states: “no space-based technology directly measures forest AGB stocks or stock-changes” (2025 guidance, Chapter 2, p. 2). This supports the distinction between sensor response and estimated biomass. Our inference is that every product must carry an observation-to-model-to-decision chain.
| Target | Available evidence | Identification and missing evidence |
|---|---|---|
| 2020 forest biomass stock within a province | ESA CCI v7.0 AGB, JAXA FNF v2.1.0 mask, administrative area, R/CF | Conditional estimate for the product-defined population; local bias, mask error and factor uncertainty remain |
| Current stock of a particular parcel | One deployed 2020 map; coarse web aggregation | Not identified for today; needs suitable dated local observations, support matching and validation |
| Historical forest flux | GFW v1.4.3 province summaries, 2001–2025 totals | Model-defined period average; not a current annual observation or a drawn-box flux |
| Monitoring-period tree-stock change | User measurements and dates; implemented TGO arithmetic | Conditional calculation; sampling uncertainty and cross-date covariance are not supplied |
| Project-attributable mitigation | Stock or loss observations alone | Not identified; applicable baseline/additionality requirements, monitoring and external review remain |
| Organizational footprint | Province inventories and satellite context | Not identified; needs organization boundary, activity records, scopes and applicable emission factors |
| Issued or retired credits | Public registry snapshot | Issuance can be read as a dated record; retirement, entitlement and transactions need their own records |
- Observe
Radar, light, field dimensions, meter readings - Infer
Biomass, stock, flux or inventory under a named model - Validate
Independent reference, error, support and transferability - Decide
Eligibility, verification, issuance or retirement
2. Evidence hierarchy, lineage and contrary findings
The literature review is targeted, not exhaustive or a PRISMA systematic review. Searches on 2 October 2026 covered ESA CCI v7 uncertainty/change, GEDI quality/transferability, biomass-validation protocols, spatial cross-validation and forest-credit counterfactuals. Primary product guides, original papers and official methodology documents were preferred. The source review log records source age, section, role and limitations. A source's recent date does not prove suitability to Thailand.
- ESA CCI v7.0: the Product User Guide, 19 March 2026, §§3.3–3.4, 4–6, describes validation, local limitations, change products and aggregation. The deployed source remains 2020; newer documentation does not refresh its observation year. Dedicated change products are candidates for research, not an integration now present in Carbona.
- CEOS validation: the 2021 good-practices protocol, chapters on reference data and validation, is the basis for the proposed support-matching and independent-reference work. A small plot and a hectare pixel are different sampling supports.
- GEDI: L4A v3, Quality Assessment and Dataset Revisions, model revision 5 June 2026; guide revision 2 September 2026, is a candidate source. A footprint biomass prediction and its standard error are not error-free ground truth. Quality fields must be read from that version; a v2.1 filtering recipe must not be assumed unchanged. No GEDI shots are ingested by this release.
- Validation dependence: Roberts et al. 2017, pp. 913–916 explain why dependent train/test samples can understate predictive error. Blocking must match the intended deployment task; a very distant holdout tests transfer, not merely interpolation.
- Contrary evidence: our NFI comparison exposes a national discrepancy. It does not isolate a measured map bias. Forest definitions and areas do not match; the 1.35–2.0× result is conditional on nesting, hypothetical extra-cover density and an allometric sensitivity. The fresh review found that the previous introduction overstated this as “measured bias”; that wording has been corrected in both languages and on the map.
Do not count agreement among products as multiple independent confirmations without checking lineage. ESA's retrieval incorporates lidar information; comparing it with GEDI can be an intercomparison with shared inputs. Independent validation needs held-out references whose measurement and training relationships are documented. The complete dependency graph remains an open audit task, so no independence is assumed.
3. Experiments executed now
The following experiments run against the deployed ledger, with exact input hashes. They are numerical diagnostics and explicitly labelled hypothetical sensitivities. None is an independent field-accuracy experiment. Re-run with npm run build; inspect scripts/scientific-audit.mjs and the machine-readable result.
Executed diagnostics on deployed data
A reproducible analysis of 77 provinces. These results test arithmetic and sensitivity; they are not field-validation results. · JSON + SHA-256 ↗
| Diagnostic | Result | Interpretation |
|---|---|---|
| National random-error half-range | ±1.36% | Block and normal assumptions; systematic bias excluded |
| Median provincial random-error half-range | ±11.34% | 77 provinces; not field RMSE |
| Hypothetical R +0.05 | +3.94% | Algebraic sensitivity; not a confidence interval |
| Hypothetical CF +0.01 | +2.13% | Calculator factors unchanged |
Two-date change depends on error correlation
Hypothetical: stock SD at each date = 10 tCO₂; observed difference = 20 tCO₂. The app does not estimate ρ.
| ρ | Hypothetical 95% half-range (tCO₂) | Difference interval includes zero? |
|---|---|---|
| -0.5 | 33.95 | Yes |
| 0 | 27.72 | Yes |
| 0.5 | 19.6 | No |
| 0.9 | 8.77 | No |
| 1 | 0 | No |
Sensitivity to grid-edge sampling
One illustrative triangle on the actual grid. 16×16 is a denser approximation, not truth or a general error bound.
| Samples per side | AGB (tonnes) | Difference from 16×16 |
|---|---|---|
| 1 | 67,709.21 | -11.93% |
| 4 | 76,104.22 | -1.01% |
| 8 | 76,765.6 | -0.15% |
| 16 | 76,878.57 | 0% |
Plan sampling without inventing a fixed plot count
CV = SD / mean; e is the target relative half-width; design effect is design variance divided by independent-sample variance. Illustrative planning: n ≈ ceil[(1.96 × CV / e)² × design effect], with e = 10%. Pilot estimates of CV and the sampling structure are required. These are not TGO minimums.
| CV | Independent units | Design effect = 2 |
|---|---|---|
| 0.3 | 35 | 70 |
| 0.6 | 139 | 277 |
| 1 | 385 | 769 |
Dataset versions used in this audit
| Dataset | Version | Period / year |
|---|---|---|
| cci | v7.0 | 2020 |
| fnf | v2.1.0 | 2020 |
| gfw | v1.4.3 (data-api v20260327) | 2001–2025 |
| gfed | GFED5.1 | 2013–2022 |
| odiac | ODIAC2025 | 2024 |
| codab | v01 (valid 2022-01-22) | — |
| climatetrace | API v7 | 2024 |
| btr1 | Thailand's First Biennial Transparency Report | 2022 |
Input hashes are in the JSON; hypothetical assumptions are separate from observations. No new model training, field additionality assessment or proof of 95% interval coverage was performed. · 2026-10-02 · afdad6a
The factor perturbations are deliberately declared before interpretation: R ±0.05 and CF ±0.01. They are not empirical standard errors or proposed replacement factors. Since S = AGB(1+R)CF(44/12), the exact relative responses are ΔR/(1+R) and ΔCF/CF. Shared factor error does not disappear when thousands of pixels are added. This is why a narrow random-map range cannot be read as total uncertainty.
For change, Var(S₁−S₀) = Var(S₁)+Var(S₀)−2Cov(S₁,S₀). Assuming independence without evidence may overstate or understate uncertainty, depending on the covariance. The synthetic experiment shows how the same apparent change can include or exclude zero under different assumed correlations. Even a statistically detectable change does not establish additionality.
The 4×4 versus 16×16 polygon difference applies to one deliberately chosen triangle. It measures sensitivity of the web-grid approximation, not error against the original 100 m raster or the true forest boundary. Conservation checks show arithmetic consistency; they cannot detect a source-wide bias.
4. The counterfactual that imagery cannot supply
Consider identical observations: stock is 100 at the start and 110 at the end. If the no-project outcome would have been 110, additional change is zero; if it would have been 105, additional change is five. The imagery alone cannot distinguish those worlds. This is a conceptual example, not a substitute equation for T-VER-S-METH-13-01 v2. Apply the approved method's actual baseline and additionality rules.
Holland 1986, pp. 945–950 provides the causal-inference distinction. In forest conservation, West et al. 2023, corrected 31 January 2024 found problems with attribution under studied baselines. A 2023 rebuttal preprint disputes aspects of that analysis. This contested literature motivates scrutiny of comparator selection and pre-trends; it does not demonstrate failure of Thai T-VER projects or supply a universal discount.
5. A validation protocol that can actually reject the model
This is a prospective protocol, documented before acquiring new validation outcomes. It is not an externally registered preregistration. The following tasks require field/reference access that is absent from this repository.
- Freeze the target. Choose a forest type, biomass pools, reporting dates, intended parcel/stratum scale and acceptable decision error with the scientific reviewer. Map the field and product forest definitions. Identify legal/credit questions separately.
- Design the sample. Use probability-based plots or a justified cluster design across the target domain, retaining zero-tree plots. Record strata, inclusion probabilities, GPS uncertainty, plot extent, date, DBH, height, species/wood-density source and disturbance history. The current CSV importer does not represent zero-tree plots; retain them in the external survey dataset. Estimate CV and design effect in a pilot; set the sample size from precision and representation, not an invented universal plot count.
- Match support and time. Resolve plot–footprint–pixel differences, terrain and geolocation. Define exclusion rules before examining prediction residuals. Document temporal mismatches and retention after each quality filter.
- Freeze splits. Reserve spatial blocks and a genuinely later-time test; keep repeated plots, flight lines and shared-reference clusters together. Estimate separation from dependence and the actual deployment range. Never tune preprocessing, features or hyperparameters on the final holdout.
- Compare candidates. Include an area/stratum mean baseline, the unchanged open product, and a simple local regression before considering a more complex model. Fit on training data only. If validation labels come from another model, call the result agreement with that model, not accuracy against nature.
- Report uncertainty and failure. Weighted bias, MAE, RMSE, calibration slope/intercept and interval coverage must be reported by stratum, biomass range and support. R² alone is insufficient. Use held-out block/cluster resampling appropriate to the design; carry reference measurement error, allometric error, mask error and temporal covariance. Small evaluation samples cannot certify nominal 95% coverage.
- Set the release gate. Before testing, record decision-specific tolerances with their owner. Reject a candidate that does not improve the intended held-out task, misses the agreed bias/coverage target, or extrapolates beyond represented conditions. Numerical tolerances have not been agreed, so this audit does not invent a “passed scientific accuracy” threshold.
- Separate publication from issuance. Publish code, factor versions, data-access conditions and failed cases. Assess approved-method requirements separately. A paper or predictive score cannot authorize credit issuance.
- Define estimand + decision tolerance
- Acquire independent, support-matched references
- Train / tune without the held-out test
- Evaluate bias, error and coverage
- Reject, restrict domain, or document a bounded release
6. What would change the conclusion?
A matched-support, independently designed Thai reference sample could quantify local map bias and show whether a locally calibrated model transfers. Paired measurements with documented covariance could validate a monitoring-change interval. An eligible project dossier and assurance opinion could support a credit submission; an issuance/retirement record could establish the registry event. None has been fabricated here.
Our own bias is the wish to make open data useful and the fact that we are auditing a system we built. A fresh reviewer was therefore given the scientific spec and source files, without the author's defence. One material overclaim was confirmed and corrected; the rest remains bounded by the unverified field, temporal and causal tests above. This is a research-strengthened pilot, not an airtight scientific guarantee.
Standards, scope & accountability
Research and assessment pilot · not certified credits. The features below support selected practices relevant to ISO standards. This is a design mapping, not a clause-by-clause conformity assessment, ISO certification or assurance opinion.
- ISO 14064-2:2019 · Project accounting
- Project boundaries, baseline and monitoring dates, named factors and reproducible exports support transparent quantification. Complete project eligibility, baseline justification and monitoring plans remain project-specific work.
- ISO 14064-3:2019 · Validation and verification
- Sources, versions, assumptions and calculation records support independent review. No independent validation or verification has been performed by this software.
- ISO 14065:2020 · Verification bodies
- Relevant when appointing an environmental-information validation or verification body. It applies to those bodies; this application is not an accredited verifier.
T-VER programme rules and the applicable approved methodology govern eligibility and issuance. Satellite stock is not a monitoring-period credit. Aerosol imagery is context, not a carbon-credit measurement.
User project files are processed in browser memory; exports are your record. Map providers receive tile requests. The server retrieves public global feeds. Source licences and dates apply. Organisation marks identify the project context; they do not establish endorsement, ISO certification or TGO approval. Standards references checked 26 September 2026.
16 · From a forest number to a place worth checking: GFW Forest Watch
A carbon estimate is more useful when it helps someone decide where to go next. GFW's portal separates discoverable datasets, source metadata, downloads and alerts. We adopt that discipline: a versioned, inspectable alert snapshot beside the carbon ledger, with a field-investigation path instead of a new claim to credits.
Implemented: gadm__integrated_alerts__adm1_daily_alerts v20261005, Thailand, 5 September–4 October 2026 (end-exclusive 5 October), filtered to is__tree_cover_2022=true. The API returns hectares and alert-pixel counts grouped by province, detection date and confidence. This is the legacy integrated deforestation-alert product (UMD/GLAD + WUR), not the newer global DIST-ALERT vegetation-disturbance product. Source metadata, download and provenance.
The rail separates nominal, high and highest confidence. Its headline is high + highest area, not an event count; its daily chart includes all confidence levels. Province buttons identify the five largest recorded high/highest areas. This is an investigation priority within the query, not a forest-risk score or normalized province comparison. Large provinces, sensor availability, weather and detection lag affect totals. The integrated grid is 10 m; resampling does not create new 10 m Landsat information. Confidence upgrades and removals of unconfirmed alerts can revise historical totals. A zero is absence of recorded detections, not proof of intact forest.
No alert is converted into tonnes, assigned to a drawn parcel, deducted from a project or treated as an issued-credit reversal. Province context remains separate from the workbench. JSON export includes the complete selected snapshot; carbon CSV retains only carbon rows. Public files include the exact query, raw SHA-256, mask, dates, attribution and CC BY 4.0 licence. The ingestion script rejects unknown provinces, unexpected confidence values, negative areas and out-of-window dates. Tests reconcile national, province and daily totals.
Reproduction: python3 scripts/ingest/gfw_watch.py --date 2026-10-05. Future refreshes must select an available dataset version and rebuild/deploy; the snapshot does not silently refresh. No user boundary is sent to GFW. The public CSV download succeeded without authentication; absent CORS is handled by offline ingestion. An account subscription alone does not configure a Data API key: none is configured here. Authenticated raster ingestion remains a separate step, so drawn-area flux remains unavailable.
17 · What a carbon footprint is — and which footprint this tool measures
Short answer: a carbon footprint is an emissions account assigned to something you can name — a product, a company, a city, a country — over a stated period, inside a stated boundary. This workbench computes none of those inventories. It screens the forest carbon of a landscape. The two meet at exactly one honest point: an organization that intends to claim forest credits must first know its own footprint, and neither number is allowed to cancel the other. Reduction is claimed against the footprint; removal is claimed by the project; the credit is issued only after section 07's three gates.
The scopes, in one paragraph each
The GHG Protocol Corporate Standard (revised 2004) divided a company's emissions into three scopes, and the vocabulary stuck far beyond companies. Scope 1 is what you burn yourself: fuel in owned vehicles and boilers, process emissions, fugitive releases. Scope 2 is the energy you buy — electricity, steam, heat — accounted with dated grid factors, location-based or market-based, and the choice must be disclosed. Scope 3 is everything up and down the value chain: the Corporate Value Chain Standard (2011) names fifteen categories from purchased goods to end-of-life treatment, and in most sectors Scope 3 dominates the total. A product footprint asks the same question per unit of function through life-cycle assessment (ISO 14040/14044; ISO 14067 for the carbon claim). A territorial inventory asks it per country under the IPCC 2006 Guidelines — that is the shape of Thailand's BTR1 (2022), the same report the carbon map carries as a cross-check. Consumption-based accounting then reassigns trade: the emissions of imported goods follow the importer, not the exporter.
| Footprint | Governing standard | Unit | Period | This tool's role |
|---|---|---|---|---|
| Corporate inventory | GHG Protocol Corporate + Scope 3 · ISO 14064-1:2018 | tCO₂e per year, by scope | Reporting year | None — no activity data is collected here |
| Product footprint | ISO 14067:2018 via LCA (ISO 14040/14044) | tCO₂e per functional unit | Life cycle | None |
| Territorial inventory | IPCC 2006 Guidelines · Thailand's BTR1 (2022) | MtCO₂e per year | Calendar year | Cross-check table beside the map |
| Landscape screening | This workbench, from open data | tCO₂e stock · tCO₂e/yr flux | Each dataset's own period | The tool itself |
| Credit project | T-VER-S-METH-13-01 v2 (or the fitting method) | tCO₂e over a monitoring period | Baseline → monitoring date | Arithmetic for supplied measurements only |
- Footprint: who emitted, inside which boundary
- Reduction: change the activities
- Residual emissions remain
- Removal: a project grows or protects carbon
- Credit: only after rights, method and verification
Four rules survive every one of these frameworks, and this tool borrows each of them. Boundaries come before numbers: a footprint without a stated boundary is a mood, not an account. Scopes never cancel: a forest sink does not shrink a Scope 1 figure — exactly as the map never nets forest flux against fossil CO₂; ODIAC2025 sits beside, never inside. Factors are dated: a grid factor without its year is unusable — the same discipline that puts a version and period on every ledger row. The causal order matters: reduction comes before removal is counted, because a credit bought before any reduction is a transfer, not a claim of change.
What a footprint cannot do
A footprint is a scale, not a licence. Knowing an organization's tonnes does not make its reductions additional, its baselines defensible, or its credits real — that is section 07's territory. Conversely, a beautiful forest estimate does not shrink anyone's footprint. When a presenter shows one number to answer the other question, stop the meeting and ask which account is on screen.
18 · Climate change and Thailand's forests
Short answer: climate change is the reason this accounting exists, and it reaches Thai forests through water and fire more than through temperature alone. The most recent assessed decade (2011–2020) stood about 1.09 °C above the 1850–1900 baseline (IPCC AR6 WG1, 2021); the WMO reported 2023 as the warmest year on record at about 1.45 °C. For the current figure, read the WMO's annual State of the Global Climate — this notebook dates its knowledge and does not quote a moving number as if it stood still.
Thailand's commitments, as documents rather than slogans
Thailand's announced long-term targets are carbon neutrality by 2050 and net-zero greenhouse-gas emissions by 2065, announced at COP26 in Glasgow. The binding arithmetic lives in UNFCCC documents: the Nationally Determined Contribution registered for 2030 and the Biennial Transparency Report (BTR1, 2022) whose LULUCF table the map displays beside GFW's satellite view. Those two views differ by definition, not by error — the national inventory counts managed land under national definitions; GFW counts satellite-mapped forest ecosystems. The tool shows both and chooses neither. Read the current NDC document for the binding percentage; a slogan with a number and no boundary is not a target.
What warming does to these forests — through water and fire
The dry season sharpens: more weeks of high fire weather across the deciduous North, which is precisely the February–April peak the GFED chart shows. Drought stress lowers growth — removals — before it raises mortality — emissions; a flux average like GFW's 2001–2025 spans wet and dry regimes, so the period label on the row is doing real work. Mangroves face sea-level rise on top of the conversion pressure documented in the field observations; a mangrove project therefore carries both a carbon case and an adaptation case. And there is an accounting irony worth saying plainly: forests are Thailand's largest sink and its most climate-exposed asset. The same fire season that drives the ledger's emissions can destroy the stock a credit was issued against — which is why reversals, buffers and permanence belong to the registry's world, not to a screening tool.
- Warming shifts rainfall and lengthens the dry season
- Fire weather rises across the deciduous North
- Drought stress lowers growth first, mortality later
- GFW forest emissions rise; GFED Feb–Apr peak sharpens
- GFW removals soften
- Baseline and permanence risk for any credit
What this tool can and cannot say about climate
It can say dated things: a 2001–2025 flux average that spans El Niño and La Niña years, a monthly fire seasonality measured over 2013–2022, an official inventory table from 2022, and alerts from the last 30 days. It cannot say forecast things: no climate projection is a carbon input here, no single year is attributed to a single cause, and no scenario replaces a measurement. Climate data in this tool is context for decisions — where to look, what to verify — exactly as section 05 demanded of every other dataset.
19 · El Niño, La Niña and the burning season
Short answer: ENSO — the El Niño–Southern Oscillation — is the Pacific's multi-year rhythm, and it modulates precisely the quantities this tool charts: rainfall, fire and forest flux across Southeast Asia. The 2023–24 El Niño was the strongest since 2015–16, peaking near +2.0 °C on NOAA's Oceanic Niño Index in late 2023 before fading to neutral during 2024. For the current phase, read the ONI series itself — this notebook dates its own knowledge instead of pretending to today's value.
The index, in three sentences
NOAA's Climate Prediction Center publishes the Oceanic Niño Index (ONI): the three-month running mean sea-surface-temperature anomaly in the Niño 3.4 region (5°N–5°S, 170°W–120°W). El Niño is declared when the anomaly holds at or above +0.5 °C, La Niña at or below −0.5 °C; thresholds of +1.0, +1.5 and +2.0 grade events into moderate, strong and very strong. The index is dated, versioned and public — the same honest-envelope discipline this tool applies to every carbon number.
| Event | Phase | Approximate ONI peak | Consequence in this region |
|---|---|---|---|
| 1997–98 | Very strong El Niño | ≈ +2.4 | Indonesia's peat fires — the textbook emission episode |
| 2015–16 | Very strong El Niño | ≈ +2.6 | Severe Indonesian fire and haze year; regional drought |
| 2020–23 | Triple-dip La Niña | ≈ −1.0 to −1.3 | Three consecutive cooler events; a different fire geography |
| 2023–24 | Strong El Niño | ≈ +2.0 | Regional drought; strongest since 2015–16; faded to neutral in 2024 |
Rounded from NOAA CPC's ONI series; read the series for exact monthly values and the current phase.
What ENSO does to the numbers on this map
El Niño's fingerprint on mainland Southeast Asia is a longer, sharper dry season. Fire follows fuel moisture with a lag, so El Niño years load the February–April burning season that the GFED monthly chart shows in every year of its average. Indonesia's great fire years — 1997–98 and 2015–16 — were El Niño years; Thailand's own burning-season severity swings with the same forcing year by year, inside the average. GFW's flux figure here is a 2001–2025 mean that deliberately spans strong El Niño years, the triple La Niña and everything between. That is exactly why the tool prints the period on the label: an average that includes 2015 is not a typical year, and one dry year is not a trend.
- ENSO state: ONI at or beyond ±0.5 °C
- Rainfall shifts over Maritime and Mainland Southeast Asia
- Fuel moisture falls through the dry season
- Escaped fires multiply — the Feb–Apr peak sharpens
- GFW forest emissions rise for that year
- Wetter phase: removals recover
- Read beside the dated average — never netted into it
What ENSO is not, here
The ONI is context, not input. No ENSO phase enters the CSEQ arithmetic, the stock bands or the fire rows; a forecast is not an observation; and attributing one province's bad fire year to El Niño requires more than a correlation, because the same season carries land-management decisions inside it. The tool's role is narrower and more useful: date every quantity, show the burning season where it lives in the data, and let Forest Watch's 30-day alerts carry the recent, dated reality that an ENSO phase only partially explains.
20 · The life of a credit: issuance, transfer, retirement — and the claim it carries
Short answer: a credit is a registry entry with a serial number, a vintage and a status. Its life has four stations — issuance, holding and transfer, retirement, and the public claim — and only the retirement date tells you when the environmental argument was actually spent. Nothing in this tool performs any of these steps; sections 11–12 show one registry's issuance-side snapshot precisely so a reader can tell the stations apart when someone hands them a credit story.
The four stations
Issuance is where units come into existence: a qualified party verifies measured change against an approved methodology, and the registry mints units carrying a vintage (the monitoring period) and serials. Issued is not the same as sold, and sold is not the same as used — the T-VER snapshot in this tool shows the gap plainly: 257 registered projects, 31 with credits certified at all. Holding and transfer move ownership between registry accounts; a transfer changes who owns the argument, not the atmosphere. Double-claiming risk lives here, which is why serials exist: one unit, one claim, ever. Retirement (or cancellation) marks a unit permanently used — a held unit is an asset, a retired unit is a spent one. The claim is what the retiree then says in public, and it is the station where the market's confusion concentrates.
| Station | What changes | What must never change | Where a reader verifies |
|---|---|---|---|
| Issuance | Units come into existence | Methodology version, monitoring dates, vintage | Registry project page |
| Transfer | Owner of record | Serial, vintage, status stays unspent | Registry holding records |
| Retirement | Status: available → used, permanently | Serial, vintage, the period it was measured over | Registry retirement records |
| Claim | A public statement attaches to the retirement | Scope and period of the claim must match the unit's | The claimant's report, audited against the registry |
- Monitoring period: measured, dated change
- Verification by a qualified party
- Issuance: units minted with serials and vintage
- Holding and transfer: ownership moves, atmosphere does not
- Retirement: the unit is permanently used
- The claim: what the retirement is said to mean
Vintage, serials and the registries' own vocabulary
A vintage names the monitoring period the tonnes were measured over; a 2020-vintage credit retired in 2026 argues about 2020, not 2026. A serial (registry–project–period–batch) makes one unit traceable and non-duplicable across its whole life. Registries publish what they will publish: some list retirements publicly, and some — including TGO for T-VER — do not publish per-project transfers and retirements at all, which this tool's registry notes say outright. Where retirement records are not public, a claim cannot be independently checked against the registry, and the honest response is to say so rather than to round the gap away.
Article 6, in one honest paragraph
The Paris Agreement's Article 6 lets countries cooperate: 6.2 governs bilaterally traded internationally transferred mitigation outcomes (ITMOs), 6.4 defines a new central crediting mechanism, and both require corresponding adjustments so the selling country's inventory does not count the same tonnes its buyer claims — double counting between countries, not just between companies. Thailand's side of this machinery lives in its FREL and its BTR submissions, both referenced elsewhere in this notebook. The workbench displays none of it: Article 6 is context for reading national claims, not a calculation any map can perform.
The claim discipline
A retirement is permanent; the claim built on it is a separate artefact with its own rules. Offsetting-style claims ("this product is carbon neutral") require the retirement to match the claimed scope and period, and must follow the claim language their framework allows — ISO 14068-1:2023 now governs carbon-neutrality claims and phases them toward net-zero transition claims, and the GHG Protocol is revising how market instruments interact with scope accounting. Contribution-style claims ("we funded the restoration of X hectares, expected to remove Y tonnes over Z years") are the more defensible shape: they describe a funding act, not a cancelled debt. Five questions audit any credit claim: which registry, which serial and vintage, retired or merely held, does the claimed scope and period match the unit, and who verified the underlying change. A claim that cannot answer all five is a story, not an accounting entry.
Where this tool stops
Deliberately before all of it. The workbench screens landscapes with open data, computes supplied measurements under a named Thai method, and shows dated registry context — it issues, holds, transfers and retires nothing. The credit chapters (07, 11, 12 and this one) exist so that the distance between a satellite image and a spent serial number is never invisible to the person being asked to believe in it.
Southeast Asia · an auditable regional extension
Open the 11-country map or the regional Bible. Brunei, Cambodia, Indonesia, Lao PDR, Malaysia, Myanmar, Philippines, Singapore, Thailand, Timor-Leste and Viet Nam are included. The original Thai project workflow remains separate. The 17 new bilingual chapters cover six methods and eleven country research profiles.
Comparability is a contract
A regional comparison needs the same construct, unit, period and boundary within each column. The regional table deliberately keeps FAO forest area, GFW forest flux and EDGAR/IEA non-LULUCF CO₂ in different columns. National forest definitions, a satellite model's extent and a territorial emissions boundary are different objects. A common country code does not make them one inventory.
The ingestion script requests the exact eleven ISO3 codes and checks identity, uniqueness, finite values and period. Forest area and share use 2023, matching the displayed CO₂ year. WDI reports its own source update date separately from the observation year. The GFW source remains pinned to v20260327 for a comparable 25-year window. A refresh does not relabel those observations as 2026.
Show the arithmetic and the missingness
Forest hectares = published km² × 100. This is a unit conversion, not a biomass estimate.
Mean annual GFW quantity = reported 2001–2025 period quantity ÷ 25. Mg equals a metric tonne. Gross removals are positive quantities in their own column. Net is positive for a source and negative for a sink. The displayed net uses GFW's own reported net, with a check against emissions minus removals allowing small source rounding differences.
Regional total for metric j = Σ country j, only when all eleven country records contain that metric. If one value is absent, the regional total is withheld rather than presenting a partial sum as the whole region. Do not average country percentages. A weighted regional share would require matching land-area denominators; that headline is not implemented here.
Why no regional carbon balance?
Subtracting GFW forest removals from EDGAR CO₂ would mix a long-run forest-model mean with one year's territorial CO₂ outside LULUCF. It would omit gases and other land-use processes, and could misrepresent the model boundary. The system therefore provides context side by side and no synthesized national or regional net across sources. The only forest net is GFW's own.
What was checked, and what was not
The pipeline checks complete country geometry coverage, valid numerical values, source-internal GFW net consistency, regional sums and reconciliation of Thailand's GFW emissions/removals against the existing ledger. An independent ADM0 summary endpoint returned 404. That unavailable cross-check is recorded, not counted as a passed test. No independent field accuracy or model interval coverage has been established for the regional extension.
Each original response is hashed and cached outside the public site. The public snapshot contains its source URLs, units, dates, versions, licence and digest. The 137 kB country geometry is a rounded cartographic derivative; its areas are never substituted for FAO statistics. If a source changes definition or revises history, retain the prior snapshot and describe the revision before comparing releases.
Source versions / รุ่นข้อมูล
- FAO forest area / WDI AG.LND.FRST.K2 and forest share AG.LND.FRST.ZS: 2023 observations; WDI 2026-10-08; CC BY 4.0.
- EDGAR / IEA / WDI EN.GHG.CO2.MT.CE.AR5: 2023; CO₂ excluding LULUCF; WDI 2026-10-08; CC BY 4.0.
- GFW carbonflux_adm1_summary v20260327: forest carbon flux v1.4.3; 2001–2025; source threshold 30; CC BY 4.0.
- Natural Earth v5.1.2, 1:50m countries: public-domain orientation geometry.
- Download exact results, source URLs, hashes and checks. Rebuild script.
From a useful estimate to a reviewable decision
This is an operating protocol authored for this release, not an external validation opinion. Read the four linked methods below; their teaching arithmetic is separate from the deployed forest figures.
Choose the decision before the number
Start with the decision, not a layer
A client asks, “How much carbon is here?” Write down what “here” and “carbon” mean before opening a map. Is the decision to prioritize a field visit, report an organization's annual emissions, estimate tree biomass change, or support an application to a credit programme? These decisions need different evidence. A green map can be useful without answering all four questions.
The following is our operating decision guide, not a new accounting standard. GHG Protocol's inventory/project comparison distinguishes an inventory within a reporting boundary from the effect of an intervention against a counterfactual. A national forest model adds another scale. An issued unit needs its own registry evidence.
| Decision | Minimum evidence | Appropriate result | Stop if… |
|---|---|---|---|
| Compare countries | Same source, period, definition and unit | Dated national context | Someone interprets a country mean as a parcel measurement |
| Plan a forest survey | Boundary, ecosystem, access and proposed strata | Sampling and evidence plan | Accessible plots are treated as representative without justification |
| Estimate measured stock change | Compatible dated measurements, area and method | Conditional change estimate | Dates, units or expansion areas are incompatible |
| Compile a corporate footprint | Activities, reporting boundary and applicable factors | Inventory by scope | A forest sink is subtracted from unrelated activity emissions |
| Support a credit claim | Rights, eligible method, baseline, monitoring, review and registry evidence | Evidence pack for the relevant programme | Software output is presented as issuance |
Walk through one site
Imagine a cooperative considering ten hectares of restoration. That is a teaching scenario, not a real project. Use the map to understand the surrounding landscape. Then obtain the actual boundary and land-use history. Identify which pools and activities the applicable method covers. Design a representative survey, record dated measurements and keep the original records. A regional forest-cover percentage cannot fill those records.
Before comparing two visits, confirm that both cover the same population and area, and that tree dimensions, allometry, root treatment and carbon fraction are compatible. If methods changed, document a bridge or recomputation. Do not interpret a better map or a newly included plot as extra tree growth.
The workbench can trace supplied measurements through its implemented Thai method. It does not establish the cooperative's rights or eligibility. For another Southeast Asian country, the national screen and research profile help frame the enquiry; they do not activate a country project methodology.
Use the first session to make an evidence request
Leave the first meeting with a named decision owner, reporting period, boundary version, list of missing records, responsible data owners and review date. Ask who will be affected by field access and who can challenge the proposed interpretation. Missing records stay missing. An LLM may help organize questions; it must not invent measurements, land rights or registry serials.
A useful result can be “we can screen this location, but cannot estimate eligible credits yet.” That answer protects the next investment in evidence. Reopen the conclusion when a new boundary, local measurements, programme decision or revised source changes the question. Document the reason rather than overwriting the original result.
Work uncertainty without hiding assumptions
A precise-looking answer can still be uncertain
Separate uncertainty in measurements and parameters from uncertainty about the model and the question itself. Repeating a calculation proves that the software is deterministic; it does not prove that the input represents the forest. A narrow interval can coexist with systematic error, an unsuitable allometric equation or the wrong boundary.
The examples below are newly authored teaching calculations. They are not uncertainty estimates for Carbona's countries, forests or credit projects. The deployed landscape's own three random-error scenarios and inventory discrepancy remain separate.
Work an activity-factor example
Let illustrative activity A = 1,000 kWh and factor f = 0.50 kgCO₂e/kWh. The result is E = A × f = 500 kgCO₂e, or 0.50 tCO₂e. Suppose the standard uncertainties are u(A) = 50 kWh and u(f) = 0.05 kgCO₂e/kWh. These factors and uncertainties are hypothetical, not current grid values.
For independent inputs, a first-order propagation is:
u(E)² ≈ f²u(A)² + A²u(f)² = 0.5² × 50² + 1000² × 0.05² = 3125 (kgCO₂e)²
u(E) ≈ 55.90 kgCO₂e
Under an approximately normal, adequately supported distribution, a teaching interval using 1.96 × standard uncertainty is 390.43–609.57 kgCO₂e. Normality, large-sample approximation and independence are assumptions, not facts supplied by a spreadsheet. Correlation adds the term 2Af Cov(A,f). Do not report this interval if those assumptions cannot be defended; describe the unresolved sources instead.
Why correlation changes a forest-change result
Suppose two hypothetical stock estimates have standard uncertainties of 10 tCO₂e each. Their difference has:
u(Δ)² = 10² + 10² − 2ρ × 10 × 10
If ρ = 0, u(Δ) = 14.14 tCO₂e. If ρ = 0.8, u(Δ) = 6.32 tCO₂e. Shared errors can partly cancel in a difference. This does not justify choosing a high correlation because it gives a smaller interval. Estimate or justify the covariance with an appropriate repeated-measurement design and independent evidence. A changing sensor, forest mask, equation or sampling frame can introduce additional error that this simple example omits.
Spatial correlation matters too. Thousands of nearby pixels do not automatically provide thousands of independent observations. The deployed block-correlation scenario is a sensitivity assumption, not proof of interval coverage. Agreement between related producer products is not an independent field test.
Write a usable uncertainty statement
Record the quantity and unit, coverage period, random components, covariance assumptions, distribution, calculation method and exclusions. State whether the interval is standard uncertainty, a statistical confidence interval, a prediction interval or a scenario range; these terms are not interchangeable. Keep systematic uncertainty and boundary mismatch visible even if no defensible numerical distribution exists.
Use sensitivity analysis to decide what to measure next. Change one assumption at a time, then examine defensible joint scenarios. If the decision changes under plausible inputs, request more evidence or state the conditional decision. A programme's prescribed conservative deduction is a separate rule; it must not be invented from this teaching interval. Neither an interval nor a lower bound creates an entitlement to credits.
Prepare an evidence pack another person can reproduce
Make the calculation easy to challenge
A screenshot communicates a result. An evidence pack lets another person examine it. Build the pack while collecting records, rather than reconstructing it after a client asks how the number was obtained. IPCC's national-inventory QA/QC chapter provides a useful historical distinction between routine checks and review. The folder structure below is our practical adaptation for this system, not an IPCC submission template or a verification opinion.
Keep six connected records
| Record | What to keep | A useful rejection test |
|---|---|---|
| Decision brief | Purpose, intended audience, claim, owner and reporting period | Can the reviewer tell screening from an inventory or a credit application? |
| Boundary register | Geometry version, CRS, area basis, exclusions and rights evidence where applicable | Can the same physical extent and accounting boundary be reconstructed? |
| Input register | Original measurement or activity, unit, date, collector, evidence ID and corrections | Does each input point to a real record rather than a model-generated explanation? |
| Method register | Equation, parameter source, applicable edition, assumptions and exclusions | Can another analyst reproduce the unit conversions and know why this method applies? |
| Result and uncertainty | Unrounded calculation, display rounding, missing values, scenarios and warnings | Does a missing value remain missing in the export? |
| Review and change log | Checker, issue, resolution, date, approval scope and superseded version | Can someone recover the previous conclusion and explain the change? |
Use stable evidence IDs rather than personal names in public deliverables. Keep permission to disclose each record separate from permission to calculate with it. Landholder information and precise field locations may need controlled handling. Carbona's supplied files remain in browser memory; it does not create this archive or back it up for you. Export the result before closing or refreshing the assessment tab.
Reproduce a result without guessing
Save the original user-input JSON and any source documents in a controlled project folder. Save the landscape or regional JSON separately; those are contextual datasets, never substitutes for plot inputs. Record the application's release commit and source versions. Preserve the original byte hashes when available; a hash proves byte identity, not truth, lawful access or measurement quality.
Ask a colleague to reconstruct a small subset without verbal coaching. They should identify the quantity, boundary and period, obtain the same unrounded arithmetic within the documented tolerance, and reproduce the displayed rounding. Record any missing software version, hidden default or ambiguous unit as a defect. A copied screenshot matching another screenshot does not satisfy this check.
Review changes and corrections openly
For a corrected tree diameter, retain the original record, correction reason, responsible person and downstream results affected. For a new dataset, distinguish a statistical revision from a real-world change. Rebuild derived outputs and rerun relevant conservation and browser checks; do not hand-edit a published aggregate to make it agree.
Issue an evidence status with the deliverable: prepared, internally checked, independently reviewed, or externally accepted by a named process. These are different statements. Do not call an internal review an accreditation, ISO certification or programme approval. Define who can reopen an issue and what evidence would be needed to close it.
A complete software export still cannot contain rights or measurements that were never collected. The value of the dossier is the visible chain from claim to evidence, including the gaps.
Challenge disagreements and release claims
When two credible sources disagree
Keep both results visible. First ask whether they estimate the same quantity on the same land, in the same period, using compatible definitions and pools. Different answers can follow from different questions. A national inventory total and a satellite raster total do not identify map bias merely because their ratio is large.
Gibbs and colleagues' 2025 forest-flux paper describes revisions to a geospatial modelling framework and its uncertainty. It supports reading model versions and assumptions carefully. It does not independently validate this site's ingestion, every Southeast Asian country or any project parcel. The implemented GFW version is pinned separately in the source manifest; the paper's reporting period must not silently replace the deployed period.
Work through four possible explanations
| Possible explanation | Evidence to request | What would weaken it? |
|---|---|---|
| Different forest boundaries | Matched masks, area totals and exclusions | The discrepancy persists on identical spatial support |
| Different pools or equations | Pool definitions, root treatment and local allometry | Recomputing with compatible assumptions leaves the gap |
| Different dates or disturbance | Observation dates, losses, harvest and recovery records | Matched dates and documented changes do not explain it |
| Measurement/model error | Independent representative field evidence and error analysis | A held-out test supports the estimate within its stated scope |
This is a diagnostic agenda authored for Carbona. It is not a claim that any one explanation has been established. Avoid selecting the explanation that makes a preferred source look correct. Keep a competing hypothesis and its strongest contrary evidence in the review notes.
Design a test that can fail
Define the target population, unit of analysis, field protocol and acceptable errors before looking at held-out outcomes. Explain the tolerance in terms of the intended decision; do not invent a universal “accurate enough” percentage. Use spatial separation or appropriately blocked validation when nearby samples share information. Keep model tuning and final testing distinct. If an area is inaccessible, state what population remains untested.
Report signed bias, absolute error and the distribution of residuals at the actual decision scale, alongside sample size and sampling design. If reporting interval coverage, compare each test observation with its applicable interval and explain sampling uncertainty around the observed coverage. A good overall average can conceal poor results in mangroves, plantations or small holdings; inspect prespecified strata. Do not claim those strata were validated unless the samples support that statement.
For causal credit claims, predictive accuracy is insufficient. The baseline must address what would have happened without the activity, together with the programme's other requirements. A high-resolution picture does not observe that counterfactual.
Separate a software release from scientific acceptance
For this release, automated tests check arithmetic, provenance, dataset conservation, navigation, bilingual rendering, exports and failure handling. These checks can reject software defects. They cannot certify field accuracy, lawful rights, additionality, human usability or credit issuance. A browser screenshot is evidence of a rendered state, not a scientific validation report.
The current operational boundary is national screening across eleven countries and a supplied-measurement workbench under its stated Thai method. There is no trained regional parcel model or automatic country approval. Research should become more specific when new independent observations arrive, rather than becoming more certain merely because the interface looks finished.
Write the remaining uncertainties, the next evidence to collect, the reviewer and the date to revisit. An honest release can be operationally usable while leaving a scientific claim unproven. The failure is not having a limit; it is making that limit disappear.
What this release actually supports
| Surface | Available | Outside this implementation |
|---|---|---|
| Southeast Asia | Eleven-country dated national comparisons and exports | Regional parcel model, country project eligibility or issuance |
| Thailand | Landscape screening and supplied measurements under the stated Thai method | Field validation, legal rights or a verification opinion |
| Corporate footprint | Detailed bilingual study-design teaching | Complete CFO submission or regional emission-factor engine |
| Evidence and privacy | Source receipts, explicit downloads and browser-memory files | Automatic archive, upload or backup |
The release acceptance checks software behaviour; independent novice usability and scientific acceptance remain separate tasks. Reproducible release scope and checks.
Primary references / เอกสารต้นทาง
- GHG Protocol · Inventory and Project Accounting: A Comparative Review · 2023-12-20 · accounting distinction; historical guidance, not later standard adoption · accessed 2026-10-15
- IPCC 2006 · Volume 1 chapter 6 · QA/QC and Verification · Sections 6.1–6.8 · historical methodological reference · accessed 2026-10-15
- IPCC 2006 · Volume 1 chapter 3 · Uncertainties · Chapter 3 · propagation assumptions and quantitative uncertainty · accessed 2026-10-15
- Gibbs et al. 2025 · revised forest flux framework · ESSD 17, 1217–1243 · doi:10.5194/essd-17-1217-2025; framework, not independent validation of this deployment · accessed 2026-10-15